Supra2-IMG Image Generation Model: Our Generated Images, File List
Sample outputs are available on the model card.
At a Glance
| Item | Value |
|---|---|
| Repository | SupraLabs/Supra2-IMG |
| Published | 2026-09-21 |
| License | apache-2.0 |
| Source type | Primary source (the publisher itself) |
Values determined by this site’s code when the information was collected. Dates are JST.
What we checked ourselves
- We generated images on our own server and show the first results unedited.
Details and conditions are in “Our Own Measurements” below.
Overview
SupraLabs has released “Supra2-IMG", an extremely lightweight text-to-image generation model trained from scratch using high-quality synthetic datasets. This model is designed to provide state-of-the-art (SOTA) image quality for its scale, despite having a very small size of approximately 100M (100 million) parameters.
Specifications
The main specifications and architecture of the model are as follows:
- Architecture: Diffusion Transformer (DiT) / SupraDiT
- Parameter count: 104.1M
- Input: Text
- Output resolution: 256²
- Latent size: 32²
- Patch size: 2
- Text encoder: Flan-T5-Base (frozen)
- VAE: SD-VAE-FT-MSE
- Recommended sampling settings:
- CFG scale: 3.0 – Steps: 50 – Seed: 0
- Model configuration details:
D_MODEL: 576 –DEPTH: 14 –N_HEADS: 9 –HEAD_DIM: 64 –MLP_RATIO: 4.0 –D_CTX: 768 –VAE_SCALE: 0.18215
- License: apache-2.0
Performance and Quality
Supra2-IMG was trained for 10 epochs using the “LucasFang/FLUX-Reason-6M" dataset, which contains 5.6M (5.6 million) images. In the data preparation process, specific priorities are established for prompt selection in order to maximize the quality of the data used for training. Specifically, prompts are selected in the order of caption_composition, caption_entity, caption_text, caption_style, and caption_imaginative, functioning as a fallback when the preceding prompt is unavailable, thereby strictly managing pre-training to use only the highest quality data.
Regarding the training environment, it is reported that training was completed in a total of 9 hours, including data preparation time, using a single Nvidia H100 SXM 80GB (Runpod Pod). Additionally, 2.5TB of disk space was used for the training.
According to the model card, it achieves SOTA (State-of-the-art) quality at this extremely small parameter count of 104.1M. While specific numerical benchmark comparisons are not provided, it is emphasized that the combination of high-quality synthetic data and an efficient DiT architecture yields high generation capability relative to the model size.
Strengths and Use Cases
Supra2-IMG is a text-to-image (T2I) model whose greatest feature is achieving SOTA-class quality relative to its model size with an extremely small parameter count of just 104.1M. This is largely attributed to the rigorous preparation standards applied to the high-quality synthetic dataset containing 5.6M images, “LucasFang/FLUX-Reason-6M", during the training process.
Specifically, a fallback method is adopted in the data preparation stage where the quality of prompts is evaluated in the order of caption_composition, caption_entity, caption_text, caption_style, and caption_imaginative, and the next prompt is used only if the quality of the previous stage is not met. Through this process, the model is trained exclusively on the highest quality data, which is expected to result in high-precision image generation even with limited computational resources and memory capacity.
Generation is currently intended for English (en), and plans have been indicated to evolve into a next-generation model such as “Supra2.5-IMG" in the future. It will serve as a very strong option for engineers who value local execution and seek high-quality generation while remaining lightweight.
Distributed Files
Weight files published in SupraLabs/Supra2-IMG, listed by this site from the Hugging Face API. Sizes are the actual file sizes.
| File | Size |
|---|---|
model_final_ema.pt |
417MB |
How to Get It
The model can be used via the inference script provided in the Hugging Face repository. The distribution format combines the script and the model weight file (model_final_ema.pt).
First, run the following commands to create a working directory and obtain the inference script inference.py.
# Create project directory
mkdir Supra2-IMG
cd Supra2-IMG

# Download inference script
wget https://huggingface.co/SupraLabs/Supra2-IMG/resolve/main/inference.py
Next, you can start image generation using the python inference.py command. During execution, in addition to the --prompt argument describing what you want to generate, you can specify options such as --seed to ensure reproducibility, --cfg (recommended value: 3.0) to control generation quality, and --steps (recommended value: 50) to determine sampling precision. Additionally, --n to indicate the number of images to generate and --out to specify the output filename are also available.
python inference.py --prompt "a sea jellyfish floating in the pitch-black ocean depths" --seed 0 --cfg 3.0 --steps 50 --n 1 --out jellyfish.png
The execution logs display details such as the device being used, the loaded checkpoint, the model parameter count, the loading status of the text encoder (Flan-T5-Base), and the sampling process (Euler flow).
Note that downloading this model does not require a license agreement (gated access) on Hugging Face.
Can You Run It Locally?
License — apache-2.0 (Commercial use allowed): Permits commercial use, modification and redistribution. Redistribution requires including the license and stating changes; includes a patent grant.
Compiled by this site’s code from the published formats and the license field. License summaries are not legal advice — check the publisher’s original terms before relying on them.
Our Own Measurements
Values we measured ourselves on our server (no GPU) by actually reading and running this model’s files — not figures copied from the model card. How we measure, and the results for every model: Our Measurements.
Images We Generated
Generated on our CPU-only server (Neoverse-N1, 3 threads) by running SupraLabs/Supra2-IMG (apache-2.0 license) with the publisher’s inference code (Supra2-IMG inference.py, commit 10dec6e), inside an isolated environment with no network access during generation: 256×256 pixels, 50 steps, guidance scale 3.0, seed 0, fixed prompts without people, logos or text, generated 2026-09-30 (JST). Not edited or selected — this is the first image for each prompt.
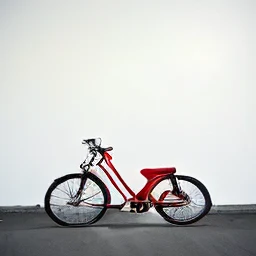
Prompt: “a red bicycle leaning against a white wall on a quiet street, soft morning light, photograph” (46.0 s to generate)
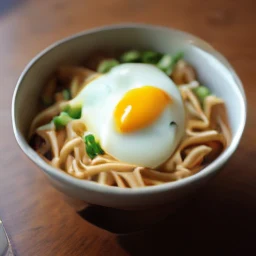
Prompt: “a bowl of ramen with a soft-boiled egg and green onions on a wooden table, top view, photograph” (46.0 s to generate)
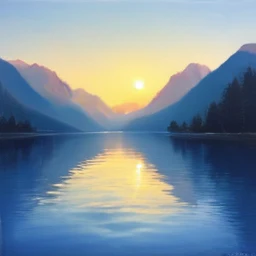
Prompt: “a mountain lake at sunset with the mountains reflected in calm water, oil painting” (46.0 s to generate)
Setup and Run Steps (What We Actually Ran)
These are the exact commands we ran from one working folder on our server (Linux aarch64, Python 3.12.3). Because we run the publisher’s code in an isolated environment, steps 1 and 2 had network access and step 3 had none. We built the environment in step 1 once and reuse it.
# 1. Build the environment (CPU PyTorch and dependencies)
python3 -m venv venv
venv/bin/pip install --index-url https://download.pytorch.org/whl/cpu -c constraints.txt torch
venv/bin/pip install -c constraints.txt transformers diffusers safetensors huggingface-hub sentencepiece pillow numpy tqdm

# 2. Download the publisher's code and the weights (pinned revisions)
venv/bin/hf download SupraLabs/Supra2-IMG --revision 10dec6e4b4b5d1c44fd1d7d3fe5e50137333da5b --include inference.py --include model_final_ema.pt
venv/bin/hf download google/flan-t5-base --revision 7bcac572ce56db69c1ea7c8af255c5d7c9672fc2 --include config.json --include generation_config.json --include model.safetensors --include special_tokens_map.json --include spiece.model --include tokenizer.json --include tokenizer_config.json
venv/bin/hf download stabilityai/sd-vae-ft-mse --revision 31f26fdeee1355a5c34592e401dd41e45d25a493 --include config.json --include diffusion_pytorch_model.safetensors

# 3. Generate
venv/bin/python supra2_img.py job.json out
constraints.txt pins every dependency to the versions installed in our environment (pip freeze, full text below). On a machine with an NVIDIA GPU, replace the --index-url of the first pip install with the PyTorch index for your CUDA version.
The generation script (supra2_img.py, written by us; it calls the publisher’s inference code in inference.py: SupraDiT). Comments are in Japanese as in our repository:
"""
Supra2-IMG で、固定のプロンプトから画像を作る(Local Model Watch の実測。記事にこのファイルの全文を載せている)。

    python supra2_img.py <job.json> <出力フォルダ>

配布元の inference.py から SupraDiT(モデルの定義)だけを読み込み、サンプリング(Euler 法・CFG)は
配布元と同じ手順をここに書き直している。重みは先に hf download で同じ版を取っておく(当サイトでは
このスクリプトをネットワークの無い環境で動かすので、ここでは取りに行かない)。重みは weights_only で読む。
出力は <id>.png と result.json(生成にかかった秒数など)。
"""
import importlib.util
import json
import os
import sys
import time

def main() -> int:
    with open(sys.argv[1], encoding="utf-8") as f:
        job = json.load(f)
    out_dir = sys.argv[2]
    os.makedirs(out_dir, exist_ok=True)
    import numpy as np
    import torch
    from diffusers import AutoencoderKL
    from huggingface_hub import hf_hub_download
    from PIL import Image
    from transformers import AutoTokenizer, T5EncoderModel

    torch.set_num_threads(int(job["threads"]))
    run = job["runs"][0]
    model = run["model"]
    extra = {d["repo"]: d for d in job["downloads"]}
    t5 = extra["google/flan-t5-base"]
    vae_repo = extra["stabilityai/sd-vae-ft-mse"]

    spec = importlib.util.spec_from_file_location(
        "supra_inference", hf_hub_download(model["repo"], "inference.py", revision=model["revision"]))
    supra = importlib.util.module_from_spec(spec)
    spec.loader.exec_module(supra)

    started = time.time()
    net = supra.SupraDiT().eval()
    state = torch.load(hf_hub_download(model["repo"], "model_final_ema.pt", revision=model["revision"]),
                       map_location="cpu", weights_only=True)
    cfg_state = state.get("config", {}) if isinstance(state, dict) else {}
    weights = state["ema"] if "ema" in state else state.get("model", state)
    net.load_state_dict(weights, strict=True)
    ctx_len = int(cfg_state.get("ctx_len", supra.MAX_CTX_LEN))
    tokenizer = AutoTokenizer.from_pretrained(t5["repo"], revision=t5["revision"])
    text_model = T5EncoderModel.from_pretrained(t5["repo"], revision=t5["revision"]).eval()
    vae = AutoencoderKL.from_pretrained(vae_repo["repo"], revision=vae_repo["revision"]).eval()
    load_sec = round(time.time() - started, 1)

    steps = int(job["steps"])
    cfg = float(job["cfg"])
    items = []
    with torch.no_grad():
        for item in run["items"]:
            t = time.time()
            tok = tokenizer([item["prompt"]], padding="max_length", truncation=True, max_length=ctx_len,
                            return_tensors="pt")
            ctx = text_model(**tok).last_hidden_state.float()
            mask = tok["attention_mask"].float()
            if "uncond_text" in cfg_state:
                u_ctx = cfg_state["uncond_text"].float().unsqueeze(0)
                u_mask = cfg_state["uncond_mask"].float().unsqueeze(0)
            else:
                u_tok = tokenizer([""], padding="max_length", truncation=True, max_length=ctx_len,
                                  return_tensors="pt")
                u_ctx = text_model(**u_tok).last_hidden_state.float()
                u_mask = u_tok["attention_mask"].float()
            ctx_all, mask_all = torch.cat([ctx, u_ctx], 0), torch.cat([mask, u_mask], 0)
            torch.manual_seed(int(job["seed"]))
            z = torch.randn(1, supra.LATENT_CH, supra.LATENT_SIZE, supra.LATENT_SIZE)
            dt = 1.0 / steps
            for i in range(steps):
                tt = torch.full((1,), i * dt)
                v_cond, v_uncond = net(torch.cat([z, z], 0), torch.cat([tt, tt], 0), ctx_all, mask_all).float().chunk(2, 0)
                z = z + dt * (v_uncond + cfg * (v_cond - v_uncond))
            image = vae.decode(z / supra.VAE_SCALE).sample
            image = ((image.clamp(-1, 1) + 1) / 2 * 255).round().to(torch.uint8)[0].permute(1, 2, 0).numpy()
            Image.fromarray(np.ascontiguousarray(image)).save(os.path.join(out_dir, item["id"] + ".png"))
            items.append({"id": item["id"], "seconds": round(time.time() - t)})
            print(f"[generate] {item['id']}: {items[-1]['seconds']} s", flush=True)
    with open(os.path.join(out_dir, "result.json"), "w", encoding="utf-8") as f:
        json.dump({"items": items, "load_sec": load_sec, "torch": torch.__version__}, f)
    return 0

if __name__ == "__main__":
    sys.exit(main())
The values in job.json that the script reads (as used):
{
  "runs": [
    {
      "model": {
        "repo": "SupraLabs/Supra2-IMG",
        "revision": "10dec6e4b4b5d1c44fd1d7d3fe5e50137333da5b"
      },
      "items": [
        {
          "id": "bicycle",
          "prompt": "a red bicycle leaning against a white wall on a quiet street, soft morning light, photograph"
        },
        {
          "id": "ramen",
          "prompt": "a bowl of ramen with a soft-boiled egg and green onions on a wooden table, top view, photograph"
        },
        {
          "id": "lake",
          "prompt": "a mountain lake at sunset with the mountains reflected in calm water, oil painting"
        }
      ]
    }
  ],
  "downloads": [
    {
      "repo": "SupraLabs/Supra2-IMG",
      "revision": "10dec6e4b4b5d1c44fd1d7d3fe5e50137333da5b",
      "files": [
        "inference.py",
        "model_final_ema.pt"
      ]
    },
    {
      "repo": "google/flan-t5-base",
      "revision": "7bcac572ce56db69c1ea7c8af255c5d7c9672fc2",
      "files": [
        "config.json",
        "generation_config.json",
        "model.safetensors",
        "special_tokens_map.json",
        "spiece.model",
        "tokenizer.json",
        "tokenizer_config.json"
      ]
    },
    {
      "repo": "stabilityai/sd-vae-ft-mse",
      "revision": "31f26fdeee1355a5c34592e401dd41e45d25a493",
      "files": [
        "config.json",
        "diffusion_pytorch_model.safetensors"
      ]
    }
  ],
  "seed": 0,
  "steps": 50,
  "cfg": 3.0,
  "threads": 3
}
constraints.txt (full text)
annotated-doc==0.0.5 anyio==4.15.1 certifi==2026.7.22 charset-normalizer==3.5.1 click==8.5.0 diffusers==0.40.0 filelock==3.32.3 fsspec==2026.7.0 h11==0.16.0 hf-xet==1.6.0 httpcore==1.0.9 httpx==0.28.1 huggingface_hub==1.33.0 idna==3.20 importlib_metadata==9.0.1 Jinja2==3.1.6 markdown-it-py==4.2.0 MarkupSafe==3.0.3 mdurl==0.1.2 mpmath==1.3.0 networkx==3.6.1 numpy==2.5.3 packaging==26.3 pillow==12.3.0 Pygments==2.21.0 PyYAML==6.0.3 regex==2026.9.29 requests==2.34.2 rich==15.0.0 safetensors==0.8.0 sentencepiece==0.2.2 setuptools==78.1.0 shellingham==1.5.4 sympy==1.14.0 tokenizers==0.23.2 torch==2.14.0+cpu tqdm==4.70.1 transformers==5.17.0 typer==0.27.2 typing_extensions==4.16.0 urllib3==2.8.0 zipp==4.1.0Other Models for the Same Task
Recent image generation models covered by Local Model Watch, newest first. Grouped by the task each publisher declares on Hugging Face (pipeline_tag); the smallest VRAM tier is this site’s estimate.
- QI_2.1_AnyAngle Camera Angle Control LoRA: 48GB+ VRAM, File List (7.1B)
- Qwen-Image-2.1-viggle-turbo Image Generation Model: 48GB+ VRAM (7.1B)
- Qwen-Image-2.1 Released: Open-Weight Image Gen & Editing
See all image generation models →
Sources
Update History
- 2026-09-24: Rebuilt the article: Added a “can you run it locally?" verdict from the distribution formats, converted builds, engine registries, license terms and measured compression
- 2026-09-25: Changed the title to show what the article covers (VRAM requirements, file list, etc.).
- 2026-09-30: Added our own measurements: images we generated.
- 2026-09-30: Changed the title to show what the article covers (VRAM requirements, file list, etc.).